Criteria
How accurate are AI IELTS writing scores compared with a real examiner?
AI IELTS writing scores are not equally accurate across the four criteria. Where AI marking tracks an examiner, where it drifts, and how to use it.
11 min read
ChatGPT often scores IELTS essays higher than an examiner. Why it happens, which criterion the gap opens on, and three prompts that work better.
Yes, ChatGPT tends to overrate IELTS writing, and the gap is usually widest on Task Response rather than grammar. That is not because the model is bad at English; it is because a general-purpose assistant is built to be helpful in conversation, and an examiner's job is something else: placing a script against fixed descriptors, criterion by criterion, including the parts that hold it down.
If ChatGPT told you "this is a solid band 7.5" and your result came back 6.5, this article explains where that gap usually comes from, which of the four criteria it opens on, and how to ask ChatGPT questions it can actually answer reliably.
A chat reply and an examiner can read the same essay very differently.
The pattern is familiar to anyone who reads IELTS forums. A candidate pastes an essay into ChatGPT, asks "what band is this?", and gets a warm, specific-sounding answer: strong vocabulary, clear structure, a band in the high sevens. Then the official result arrives half a band or a full band lower, and the candidate wonders whether the examiner was harsh.
Usually the examiner was not harsh. The two readers were answering different questions.
An examiner marks each task on four criteria — Task Response (Task Achievement in Task 1), Coherence and Cohesion, Lexical Resource, and Grammatical Range and Accuracy — and awards a whole band on each. The four are averaged into the task band, and your Writing band combines the two tasks with Task 2 counting double: (Task 1 + Task 2 × 2) ÷ 3. Every step is anchored to the published descriptors, and the descriptors include negative features. The public Task 2 descriptors say it plainly: "A script must fully fit the positive features of the descriptor at a particular level."
A chatbot asked for "a band" does not have to do any of that. It can produce a plausible number from an overall impression of the essay, and overall impressions of fluent writing are generous. So the honest answer is: ChatGPT often lands above the examiner, not always and not by a fixed amount, and the reasons are structural, which means you can work around them.
None of these is a flaw peculiar to one product or version. They follow from what a general assistant is designed to do.
1. It is tuned to be helpful and encouraging to the person asking. Conversational assistants are trained to respond in a way the user finds useful and pleasant. When the user is a student who has just written an essay, "useful and pleasant" leans toward praise, reassurance and a score that does not deflate. An examiner has no such pull. The examiner never meets you and is trained to find the weakest evidence in the script as carefully as the strongest.
2. It can quote the descriptors without applying them. Ask ChatGPT to "mark this using the IELTS band descriptors" and it will often reproduce descriptor language convincingly. But quoting "a clear and developed position is presented" is not the same as checking whether this essay's position is clear and developed. Examiners work by best fit: for each criterion they test the script against a band's description, move up or down, and settle where the evidence as a whole fits. Negative features limit a rating — an essay with band 7 grammar but only partial coverage of the prompt cannot be carried to 7 in Task Response. A single-pass answer that jumps from "reads well" to a number skips that procedure, and skipping it almost always removes the downward checks.
3. Clean grammar creates a halo. A fluent, nearly error-free essay produces a strong first impression, and that impression spreads. Once the sentences look accurate and the vocabulary looks advanced, it is easy to assume the argument is as good as the prose. Human readers are vulnerable to this too, which is exactly why examiners are trained to mark the four criteria separately. The descriptors do not let a strength in one criterion pay for a weakness in another.
Put the three together and the direction of the error is predictable: upwards, and concentrated wherever the essay's problems are least visible on the surface.
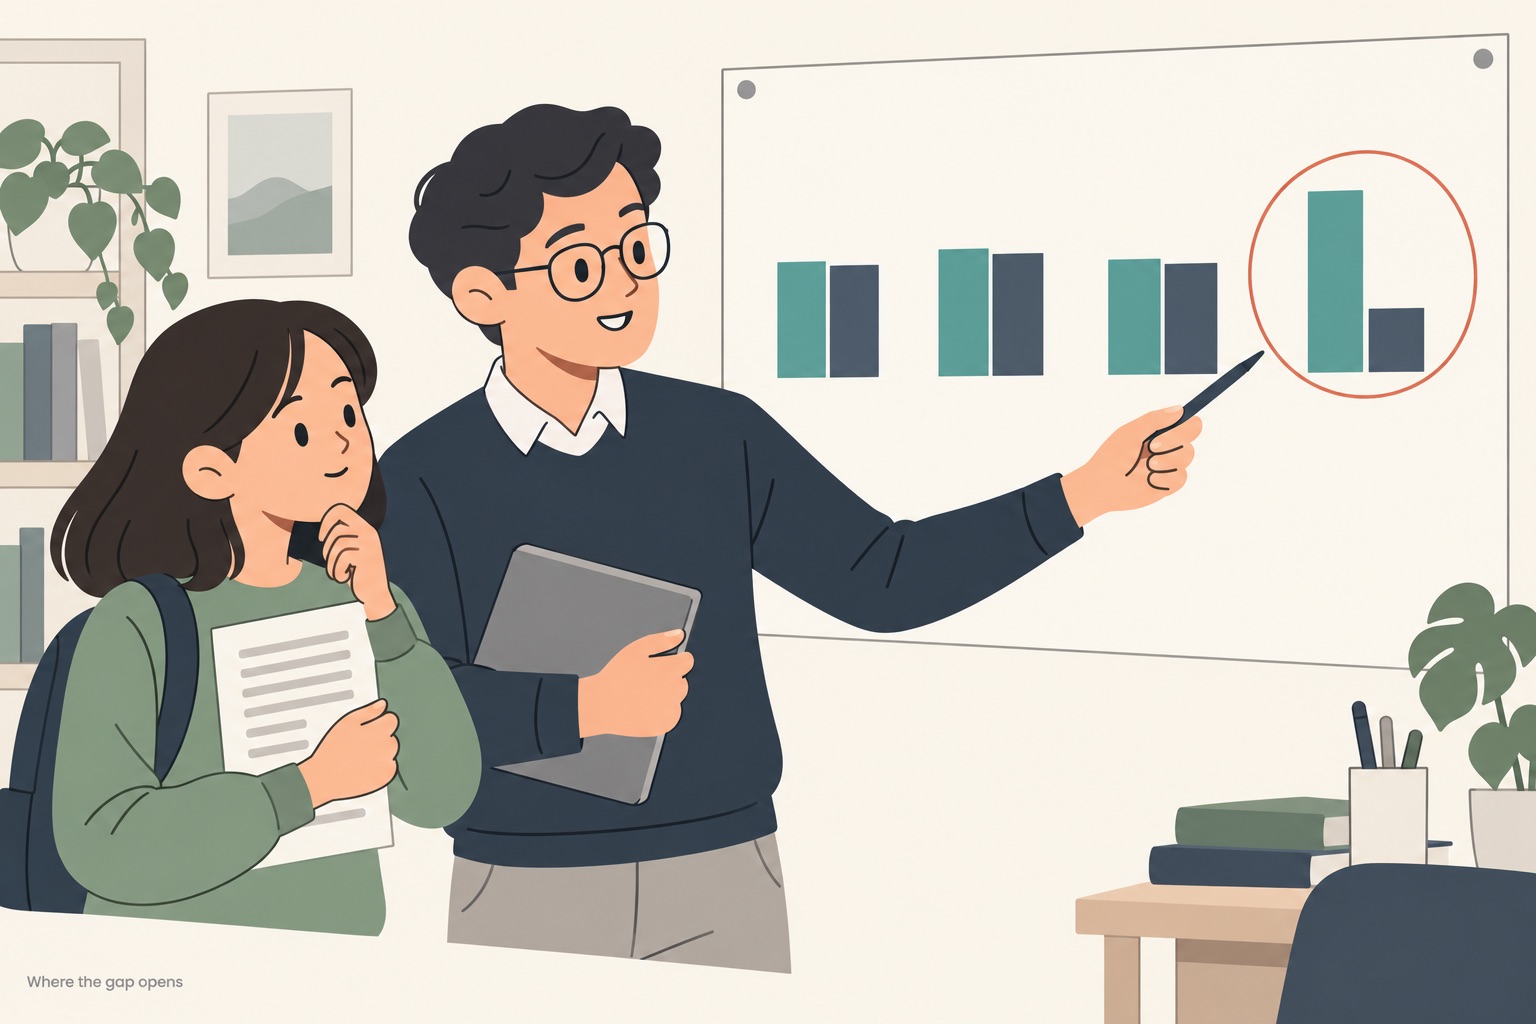
Three criteria roughly agree; the gap sits in one.
The four criteria are not equally exposed to these effects. The more a criterion depends on evidence you can point to inside a sentence, the closer a general assistant tends to get. The more it depends on reading the whole essay against the question, the further it drifts.
Grammatical Range and Accuracy: usually closest. Grammar errors and sentence structures are visible one sentence at a time. The band 7 line is: "A variety of complex structures is used with some flexibility and accuracy. Grammar and punctuation are generally well controlled, and error-free sentences are frequent." Whether a sentence has an error, and whether it is simple or complex, is a question ChatGPT answers reasonably well. Where it slips is in proportion: a handful of polished sentences can make it overlook a pattern of small article or agreement errors that runs through the rest.
Lexical Resource: close, with one blind spot. Repetition, collocation errors and register shifts are also on the surface. The blind spot is ambition. Band 7 asks for "some ability to use less common and/or idiomatic items" alongside "an awareness of style and collocation". A chatbot that rewards rare words can miss that one of them is slightly wrong in context — and an examiner will not.
Coherence and Cohesion: half and half. Cohesion is visible: linking words, reference, substitution. The band 6 descriptor warns that cohesion "may be faulty or mechanical due to misuse, overuse or omission", and an essay that opens every paragraph with Firstly, Moreover, Furthermore and In conclusion can look organised to a quick reader while matching that band 6 line exactly. Coherence — whether the ideas progress logically across the whole response — needs the whole-essay reading discussed next.
Task Response: where the gap is widest. Compare the two lines that decide most band 6 and 7 essays:
The difference is not in any sentence. It is in the relationship between the essay and the question that was set. To mark it, you have to split the prompt into its parts, decide whether each part is answered or merely mentioned, and check that one position runs from the introduction to the conclusion. An essay can use every keyword in the prompt and still answer a neighbouring question: causes instead of solutions, the topic in general instead of the specific claim, one view discussed in depth and the other in a sentence. That essay can be fluent throughout, and a general assistant asked for a band tends to converge on "well written" rather than on "did it do the task". How examiners check relevance is set out in off-topic IELTS essays.
This is also why a generous ChatGPT score and a lower official result often share one signature: the grammar and vocabulary bands would roughly agree, and the difference is almost all in Task Response.
The fix is not to stop using ChatGPT. It is to stop asking it the one question it answers least reliably — "what band is this?" — and ask questions it can answer from the text, where you can check the answer yourself.
Three prompts that do this, written for Task 2. Paste your essay and the exact question first.
Prompt 1 — map the essay to the prompt.
List every separate part of this IELTS question as a numbered list. Then, for each part, quote the sentence in my essay that answers it most directly. If a part has no sentence that answers it, write "not answered". Do not comment on quality and do not give a band.
This turns Task Response into something checkable. If any line comes back "not answered", or the quoted sentence only mentions the topic without answering it, you have found the most likely reason for a gap between a chatbot's number and an examiner's.
Prompt 2 — find my position.
In one sentence, state the position my essay takes on the question. Then quote the sentence in my introduction and the sentence in my conclusion that express it. If they express different positions, say so.
Band 7 asks for "a clear and developed position". If ChatGPT cannot state your position in one sentence, or the introduction and conclusion disagree, an examiner is likely to have the same trouble.
Prompt 3 — list errors, not impressions.
List every grammatical error in my essay as a table with three columns: the original sentence, the error, and a corrected version. Do not include style suggestions and do not rewrite sentences that are already correct.
A list of errors is more useful than "your grammar is strong", because you can count it and look for repeats. The same article error three times is a pattern, and patterns are what separate "frequent" error-free sentences from merely some.
Two habits make all three prompts more reliable: ask for quotations rather than summaries, so every claim points at text you can see; and do not ask for praise, a band or a rewrite in the same message, because each invites the encouraging, holistic answer you are trying to avoid.
Those prompts give you evidence. What they do not give you is a band per criterion that has been reached by testing the essay against each descriptor level in turn, including the negative features that hold a rating down. That is the part a general assistant skips and an examiner does not.
If you want to see where your essay sits on each of the four criteria — and which one is holding it down — paste it below. Write it the way you would on test day first: an unseen question, 40 minutes, no polishing.
Read the result in this order. Start with the lowest criterion, not the average. If it is Task Response, go back to your Prompt 1 list: the missing or thin part of the question is usually the reason. If it is grammar or vocabulary, look at the cited sentences and check each one against the descriptor line it is tied to. And if the estimate is well below what ChatGPT told you, the gap is the finding: it shows you which criterion the conversational score was not really measuring.
Like any estimate made against the public descriptors, this one is not an official band. Only a certified examiner produces that. But a criterion-by-criterion estimate you can check line by line is a far better guide to your next week of practice than one generous number. For why the gap between your own reading of an essay and an examiner's is so common, see my essay looks band 7 but scored 6.
Does ChatGPT overrate IELTS writing band scores?
It often does, though not always and not by a fixed amount. The overestimate usually comes from Task Response: a fluent, nearly error-free essay can read well while only partly answering the question, and a general assistant asked for "a band" tends to reward how the essay reads rather than whether it does the task.
Why does ChatGPT give my essay band 7.5 when I scored 6.5?
Most often because the examiner found a Task Response or Coherence problem that a quick overall reading passed over — one part of the prompt covered thinly, a position that shifts between introduction and conclusion, or linking words used mechanically. The grammar and vocabulary judgements from both readers may be quite close.
Which IELTS criterion is ChatGPT most accurate on?
Grammatical Range and Accuracy tends to be closest, because errors and sentence structures are visible one sentence at a time. Lexical Resource is usually close too. Task Response is where estimates drift most, because it depends on judging the whole essay against the question.
Can I make ChatGPT mark IELTS essays more accurately?
You can make its output more useful by not asking for a band. Ask it to map each part of the question to a sentence in your essay, to state your position in one sentence, and to list grammar errors in a table. Those answers can be checked against the text; a single band cannot.
Is an AI IELTS score the same as an official band?
No. Any AI score, including the estimates on this site, is an estimate against the public band descriptors. Only a certified examiner marking your test produces an official band.
All descriptor wording quoted here is from the public Writing band descriptors updated in May 2023, published by IELTS and the British Council.
Bandly grades your essay or letter against all four criteria and shows the gap to your target band, sentence by sentence.
AI IELTS writing scores are not equally accurate across the four criteria. Where AI marking tracks an examiner, where it drifts, and how to use it.
A band score checker can estimate your four IELTS writing criteria but not predict your test score. What it can judge, what it can't, and how to pick one.